How mixture-of-experts AI works
This article contains a paid Amazon link. I may earn a commission if you buy through it. As an Amazon Associate I earn from qualifying purchases.
A mixture-of-experts model, or MoE, has groups of learned calculations called experts.[1][2] For each small piece of text, it selects only some of those groups to do the work.[1][2] That lets the model carry more learned parameters without using every expert for every piece of text.[1][2]
What interests me is the separation: how much a model holds and how much it uses at once are different questions. That matters when you're reading an announcement, and even more when you're wondering whether an open model will fit on your own machine.[2]
This is an evergreen explanation, using the original Mixtral 8x7B as a concrete example. Mistral introduced it in December 2023; it isn't a new release.[4]
What an AI expert actually is
Start with a token: a small piece of text, which might be a word, part of a word, or punctuation.[2] Inside a language model, that token has a changing numerical representation.[1][2] In Mixtral, a router examines that representation and selects which expert blocks process it at that layer.[1][2]
An expert here is a neural-network block: learned numerical operations that transform the information passing through.[1] It isn't a little chatbot with its own conversation.[1] Mixtral's experts replace the feed-forward blocks, the parts of the model that transform each token's representation after attention has mixed in context.[1]
Attention is the mechanism that lets a token draw on other relevant tokens.[2] In Mixtral, attention and other parts of the model are shared rather than copied into eight complete chatbots.[1][2] The expert choice happens inside this larger system.[1][2]
The name needs a little care. "Experts" makes me picture a room with a mathematician, a programmer and somebody who knows plumbing. That's a useful image for dividing work, but it is a poor description of what these blocks are guaranteed to learn.
The Mixtral researchers checked routing across different kinds of documents and did not find an obvious division by topic in their analysis.[1] Their observations pointed more toward patterns in syntax, particularly near the beginning and end of the model.[1] That is evidence about this model, not a rule for every MoE.[1]
How the router divides the work
Here's a simplified pass through one expert layer:
- The layer receives the current numerical representation of a token.[1]
- The learned router scores the available experts and selects a small subset.[1]
- Those experts process the representation separately, and their outputs are combined with weights assigned by the router.[1]
In the original Mixtral, that means choosing two of eight experts at each layer for each token.[1] The next token can take a different route, and a later layer can select different experts too.[1]
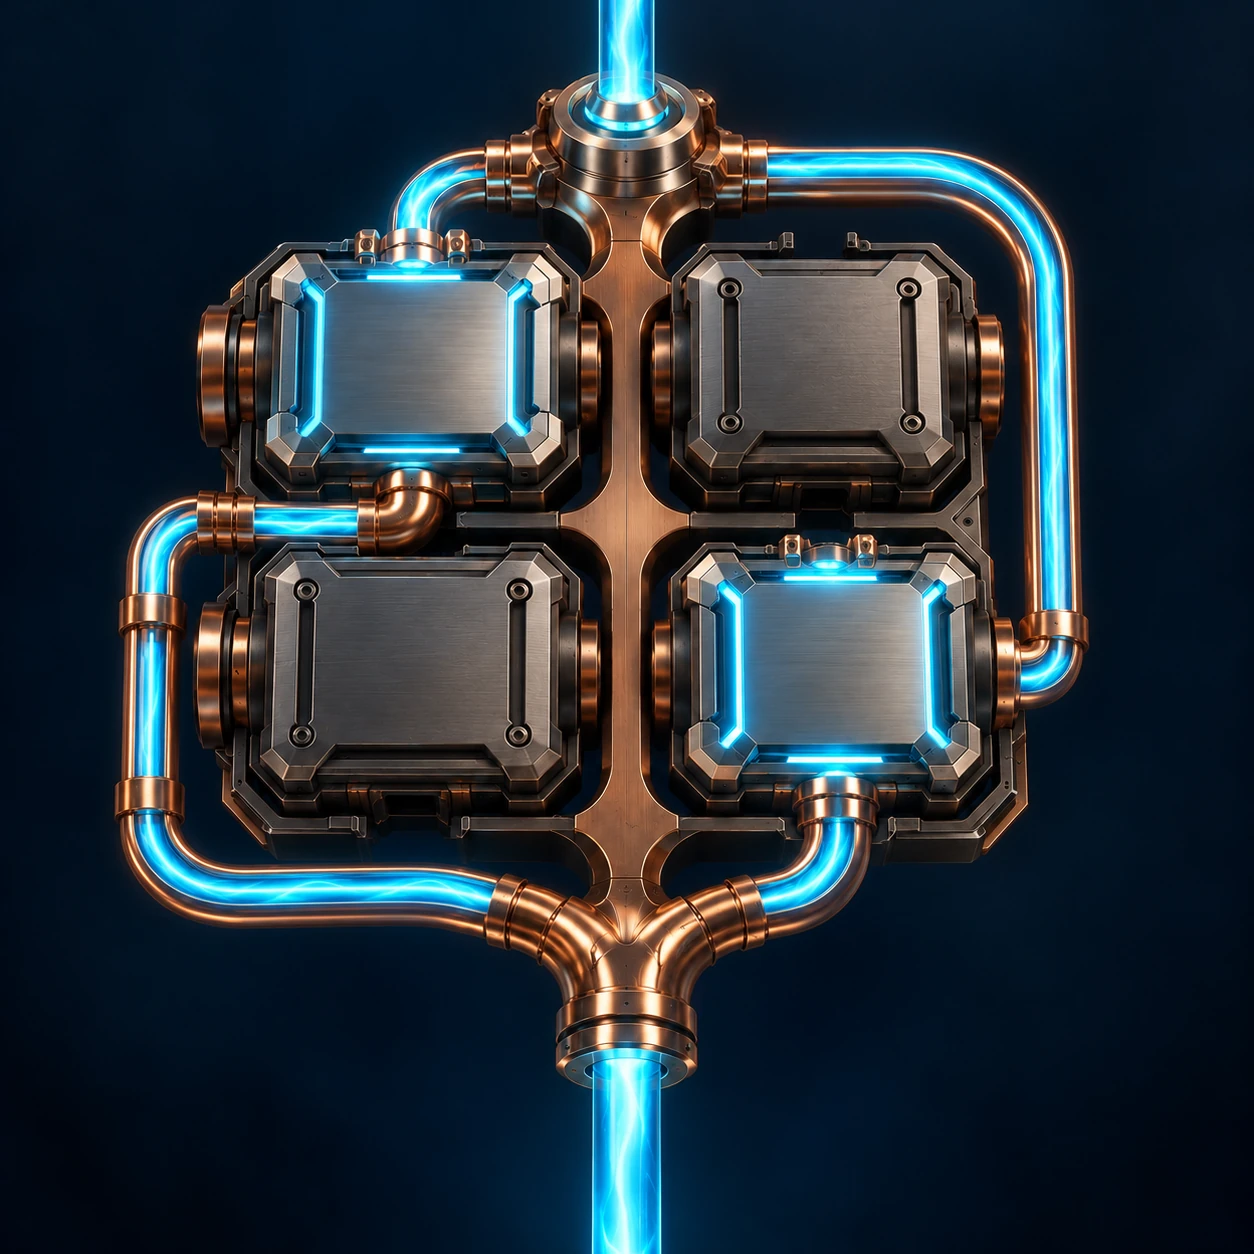
The router isn't reading the whole request and deciding to hire one specialist for the rest of the conversation. The choice in this example is much smaller and more frequent: token by token, layer by layer.[1]
That distinction also separates this architecture from an app that asks several independent assistants to answer a question. You could build such an app, but the expert blocks inside Mixtral are components of one language model.[1]
Why there are two parameter counts
A parameter is a learned number in the model.[2] Model descriptions often count them in billions.[2] With an MoE, the total parameter count and the active count per token describe different things.[1][2]
The Mixtral paper rounds those figures to 47 billion total parameters and 13 billion active per token.[1] Mistral's launch post gives the more precise figures of 46.7 billion and 12.9 billion.[1][4]
The total describes the learned numbers the model contains.[1][2] The active figure describes the subset used for a token's forward computation through the model.[1][2] It includes shared parts as well as the selected experts; it isn't simply the size of two standalone chatbots.[1][2]
This is why the "8x7B" name is easy to misread. The model does not contain eight complete, independent 7B models.[2] Shared components mean the label is not a literal multiplication giving the total parameter count.[2]
Nor is the active count a stopwatch. Routing, moving information between processors and the way software uses the hardware affect practical performance.[2] Hugging Face's technical explainer discusses those communication costs; an active parameter count alone does not tell you your laptop's response speed.[2]
The inactive experts still have to live somewhere
Before downloading anything large, this is the catch to check. Selecting fewer experts saves work on a token; it doesn't make the other experts' learned numbers disappear.[2]
Hugging Face highlights the resulting memory burden: the full set of parameters still needs accommodation, even though only a subset does expert computation for a token. In a straightforward GPU-resident setup, that means enough video memory for the full weights, not just the active count.[2]
Video memory, often called VRAM, is the memory attached to a graphics processor.[2] The total weight footprint is therefore a better starting question than the smaller active number when judging whether such a setup fits.[2]
My buying advice is boring on purpose: don't order hardware from the active parameter count. Look for requirements and measurements for the exact model, model file and software you intend to run. This article isn't a compatibility test or a hardware recommendation.
Sparse does not mean compressed
"Sparse" here means the model selects only some expert computation for an input.[2] It doesn't mean the unused experts have been removed from the model file.[2] Hugging Face discusses compression techniques separately from the routing mechanism.[2]
Keeping those ideas apart makes model announcements easier to read. A model can have a large total capacity and a smaller active path without having become a small download. A claim about reduced computation is not automatically a claim about reduced storage.
The approach also brings engineering problems. The Switch Transformers paper describes communication costs and training instability as obstacles, then presents methods to address them.[3] Those are historical research findings, not proof that every newer sparse model has the same performance or problems.[3]
What to look for in the next model announcement
I would start with the total parameter count, then the active count per token. After that, I want to know what was actually measured, on which hardware, with which software. If the announcement supplies only the smaller number, I still don't know enough to judge local fit.
I also wouldn't read "expert" as a promise of a dependable subject specialist. The original Mixtral analysis is a good reminder that the useful everyday meaning of a word can run ahead of what the researchers observed.[1]
And this is a different question from whether an assistant remembers your project. Our earlier article, How your AI remembers, separates stored chat history, working context and saved notes.[5] Choosing a computational route doesn't establish that your project decisions will survive the next session.
The idea worth keeping is fairly simple: a model can contain more learned machinery than it runs for one token. Once you separate those two things, the headline numbers become a lot less mysterious.